A patch management policy is a concise governance document that assigns ownership, sets risk‑based SLAs by severity, requires an exception register with expiry dates, and mandates rescan verification. Most organizations assign ownership to IT operations or a named maintenance owner, not “IT” in the abstract. Three outputs make the policy usable: a defined scope, a severity‑based SLA table, and a living exception register that gets reviewed on a schedule.
TL;DR:
- A patch management policy should include a living exception register with expiry dates to prevent temporary exceptions becoming permanent vulnerabilities.
- Asset inventories must reconcile agent-based discovery with network-based sources to classify devices by criticality, exposure, and business value for effective patch prioritization.
- Patches should follow a lifecycle of identification, testing, pilot deployment, and verification, with rescans serving as proof of remediation rather than just installer success reports.
- SLA targets for patch severity levels typically range from 24–72 hours for critical issues to 30 days for medium severity, with faster escalation if assets are actively exploited.
- Regular reviews of ownership, exception status, and SLA compliance, along with adherence to NIST and CISA guidance, are essential for an effective, auditable patch management program.
A patch management policy exists to reduce the window between “a vulnerability is disclosed” and “it’s fixed.” NIST frames this as preventive maintenance rather than a one-off IT chore, and that distinction matters for budgeting: preventive maintenance gets a recurring line item, not a scramble every time a CVE makes headlines.
Scope is where most policies quietly fail. A document that only mentions “servers and workstations” leaves gaps that attackers exploit. Your scope section needs to name every asset category explicitly:
Scope also needs to state which environments are covered (production, staging, test) and which ownership models apply. A corporate laptop, a BYOD phone, and a contractor’s workstation each carry different patch obligations, and a policy that treats them identically usually breaks down in practice.
Vague ownership is the single most common reason patch policies fail in practice. Four roles need distinct, written responsibilities:
Emergency patches need their own escalation path. When a critical vulnerability is being actively exploited, waiting for the next scheduled Change Control Board meeting defeats the purpose. Build a fast-track approval where the maintenance window owner and security liaison can jointly authorize an out-of-cycle deployment, with the CCB notified rather than asked to convene.
Pro Tip: Put names, not titles, in your accountability matrix. “IT Manager” changes when someone quits; “Sarah Chen, reviewed quarterly” forces the document to stay current.
A simple accountability matrix, reviewed every quarter, keeps this from decaying into “everyone assumed someone else was watching that server.”
You can’t patch what you can’t see, and manual spreadsheets fall out of date within weeks. An authoritative inventory needs at least two reconciled sources: an agent-based discovery tool that reports installed software and patch levels, and a CMDB or DHCP reconciliation process that catches devices the agent missed, including anything that connected to the network once and never got decommissioned.
Once the inventory is accurate, classify every asset along three dimensions:
Classification feeds directly into maintenance groups. NIST recommends assigning assets to maintenance groups with defined maintenance plans and risk-response scenarios, rather than treating the whole fleet as one undifferentiated pool. A maintenance group might be “internet-facing production servers,” with a plan that specifies a shorter testing window and mandatory rollback capability, versus “internal test lab,” where patches can wait for the next monthly cycle. Grouping this way turns a chaotic list of thousands of devices into a manageable set of repeatable plans.
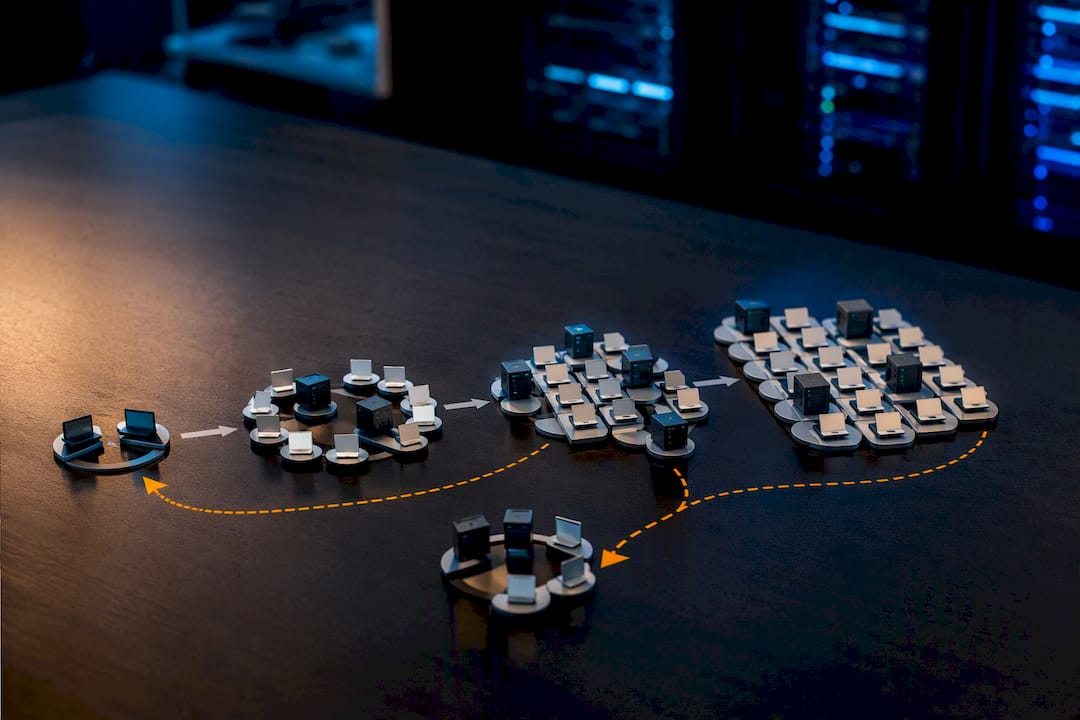
A patch management policy needs to walk through the full lifecycle, step by step, so nobody improvises under pressure:
This lifecycle needs to talk directly to your vulnerability management process. A vulnerability scan that identifies a gap should automatically generate a patch ticket, not sit in a report that a human reads once a month. Similarly, deployment steps should run through the same change control process as any other production change, with the maintenance window owner signing off before anything touches a live system.
Staged rollouts deserve to be the default, not the exception. A pilot ring of five to ten representative devices catches most compatibility problems before they hit the whole fleet, and it costs almost nothing in extra time if it’s built into the schedule from the start rather than added as an afterthought.
Severity should set the clock, not convenience. A workable starting framework looks like this:
| Severity | Target SLA | Typical trigger |
|---|---|---|
| Critical / actively exploited | 24–72 hours | Exploit confirmed in the wild, internet-facing asset |
| High | 7–14 days | High CVSS score, no confirmed exploit yet |
| Medium | 30 days | Moderate impact, limited exposure |
| Low | Next scheduled cycle | Minor issue, no exploit path identified |
Accelerate any of these timelines the moment two conditions are both true: the asset is internet-facing, and there’s evidence of active exploitation. That combination is the fast-path trigger regardless of what the base SLA says.
The patch reality gap: Telemetry on Microsoft patches shows a median install time of roughly 7.7 days (about 185 hours), with a much longer P90 tail. That means one in ten devices in a typical fleet takes dramatically longer than the median, and that tail is usually where breaches happen.
Track three metrics, not one. Median time-to-patch tells you how the typical device behaves. P90 tells you how bad the slowest 10% really is. Percent-current-within-X-days gives leadership a single number for a dashboard. Reporting median alone hides the exact devices most likely to get exploited.
Testing isn’t optional, even under SLA pressure. CISA’s recommended practices call for validated testing, verified backups, and staged deployment before a patch reaches production, specifically because a bad patch can cause more downtime than the vulnerability it was meant to fix.
Before any production deployment, confirm:
Pro Tip: Write your rollback decision tree before the patch window opens, not during an incident. “If X breaks, do Y” takes thirty seconds to read under pressure and an hour to invent from scratch.
Uptime-sensitive environments, particularly industrial control systems, need extra caution. CISA notes that ICS environments tolerate far less downtime than typical IT systems, so staged swap-to-standby procedures often replace a straightforward in-place patch.
An exception without an expiry date quietly becomes a permanent vulnerability. That’s the single most consistent warning from practitioners who’ve watched “temporary” exceptions sit unpatched for years, and it’s why the exception register needs to be a living document, not a one-time sign-off.
Every exception entry needs five mandatory fields:
Review the register on a set cadence, monthly for smaller organizations, and treat any exception past its expiry as an audit finding. End-of-support software deserves special handling: log it as a permanent exception with a mandatory replacement plan and a hard retirement date, since no compensating control fully substitutes for a vendor that no longer ships fixes.
An installer reporting “success” isn’t proof a vulnerability is closed. Rescan verification, running a follow-up vulnerability scan against the patched asset, is the evidence auditors and cyber insurers actually want to see, and it catches the surprisingly common case where a patch installs but fails to remediate the underlying flaw.
Build reporting around three dashboards:
For an insurer or an audit, the 7.7‑day median patch time reported in Acronis telemetry is a useful external benchmark against your own numbers. Retain change records, test results and rescan evidence for a defined period, commonly a minimum of one year, since audit and cyber insurance reviews frequently ask for evidence spanning that full window.
Building each clause with a named reference behind it turns your policy from an internal preference into something you can defend in an audit conversation.
Cross-referencing these sources in your policy document isn’t just good form. It gives your team language that regulators and insurers already recognize.
Watching organizations run patch programs for years surfaces the same three failure points repeatedly, and none of them are technical.
Permanent exceptions are the biggest one. The fix isn’t a stricter rule, it’s a review cadence enforced by calendar reminders tied to the exception register, so an expired entry becomes visible rather than forgotten.
Tail devices are the second. The slowest 10% of a fleet accounts for a disproportionate share of breach risk, and managing that tail explicitly as its own queue, with named owners and weekly check-ins, closes it faster than chasing median improvements.
Smaller organizations often assume they need a dedicated full-time patching role. In practice, what they need is named ownership for windows and exceptions, with execution handled through a co-managed arrangement. A quick rollout checklist:
If you strip every clause out of a patch policy and keep exactly one, keep the exception register with expiry dates. Every other failure I’ve seen trace back to an exception that was supposed to be temporary and quietly became permanent because nobody was forced to look at it again.
A copyable starting checklist:
If your team is drafting this from scratch and wants a second set of eyes before it goes to audit, NetFusion Designs Inc works through exactly this kind of build with clients regularly.
— Geeshan
A written policy is only as good as the operations behind it, and that’s usually where internal teams run out of hours. A managed service provider can operate as the maintenance window owner and implementer your policy needs, running managed patching, security operations, and pilot-ring deployments through a 24/7 NOC, so your exception register and SLA table are backed by an actual team watching the tail, not a document sitting in a shared drive.
That backing matters most at audit time. A managed service provider can provide the rescan verification, SLA compliance reporting and change records that insurers and auditors ask for, drawn from real operational history rather than a one-time policy write-up. For organizations that want ownership handled without hiring a dedicated patching role, our managed IT services in Kitchener and Waterloo build the accountability matrix, exception register, and SLA tracking into day-to-day operations from week one. If your policy is written but nobody’s executing it consistently, that’s the gap worth closing next. Book a consultation to review what your current patching posture would look like under an audit.
It’s a governance document that defines who owns patching, how quickly patches must be applied based on severity, and what evidence proves a vulnerability was actually closed. It also requires an exception register to track any patch that can’t be applied on schedule.
Treat patching as ongoing preventive maintenance rather than a reactive task, assign assets to maintenance groups with defined plans, test before deploying to production, and verify results with a rescan rather than trusting installer logs. NIST SP 800-40 and CISA’s recommended practices both converge on this approach.
NIST SP 800-40 Rev. 4 recommends framing patching as preventive maintenance, defining explicit scope across asset types and environments, grouping assets into maintenance groups with risk-response plans, and automating discovery and deployment wherever the organization’s scale requires it.
The core process runs through eight steps: identify, prioritize, acquire, test, pilot, deploy, verify and close. Each step should connect to vulnerability scanning and change control, so a discovered gap turns into a tracked ticket rather than a note in a report nobody revisits.
A common risk-based target is 24 to 72 hours for critical or actively exploited vulnerabilities on internet-facing assets, 7 to 14 days for high severity, and 30 days for medium severity. Organizations should track both median time-to-patch and the P90 tail, since telemetry shows a median around 7.7 days with a much longer tail for the slowest devices.